A few years ago, much of the conversation about artificial intelligence in law revolved around one question:
Can AI replace a lawyer?
In 2026, that question is beginning to change.
The more important questions are increasingly about something else: What sources support an AI-generated answer? Where are the boundaries of the system’s competence? How can its output be verified? And who remains responsible for the final decision?
Recent developments across the Legal AI market suggest that this shift is no longer theoretical.
It is becoming architectural.
Google moves toward specialized Legal AI
On August 25, 2026, Google Cloud introduced Gemini Enterprise for Legal, a specialized environment designed for legal work.
The important part is not simply that Google entered the legal AI market.
More significant is the architecture behind the product.
Professional legal work cannot rely on a general-purpose model alone. Legal organizations need controls around confidential information, permissions, specialized workflows, access to professional systems, governance, and oversight.
This points toward a broader transition.
The early model of Legal AI could be summarized as:
“Ask a large language model a legal question.”
The emerging model is considerably more complex:
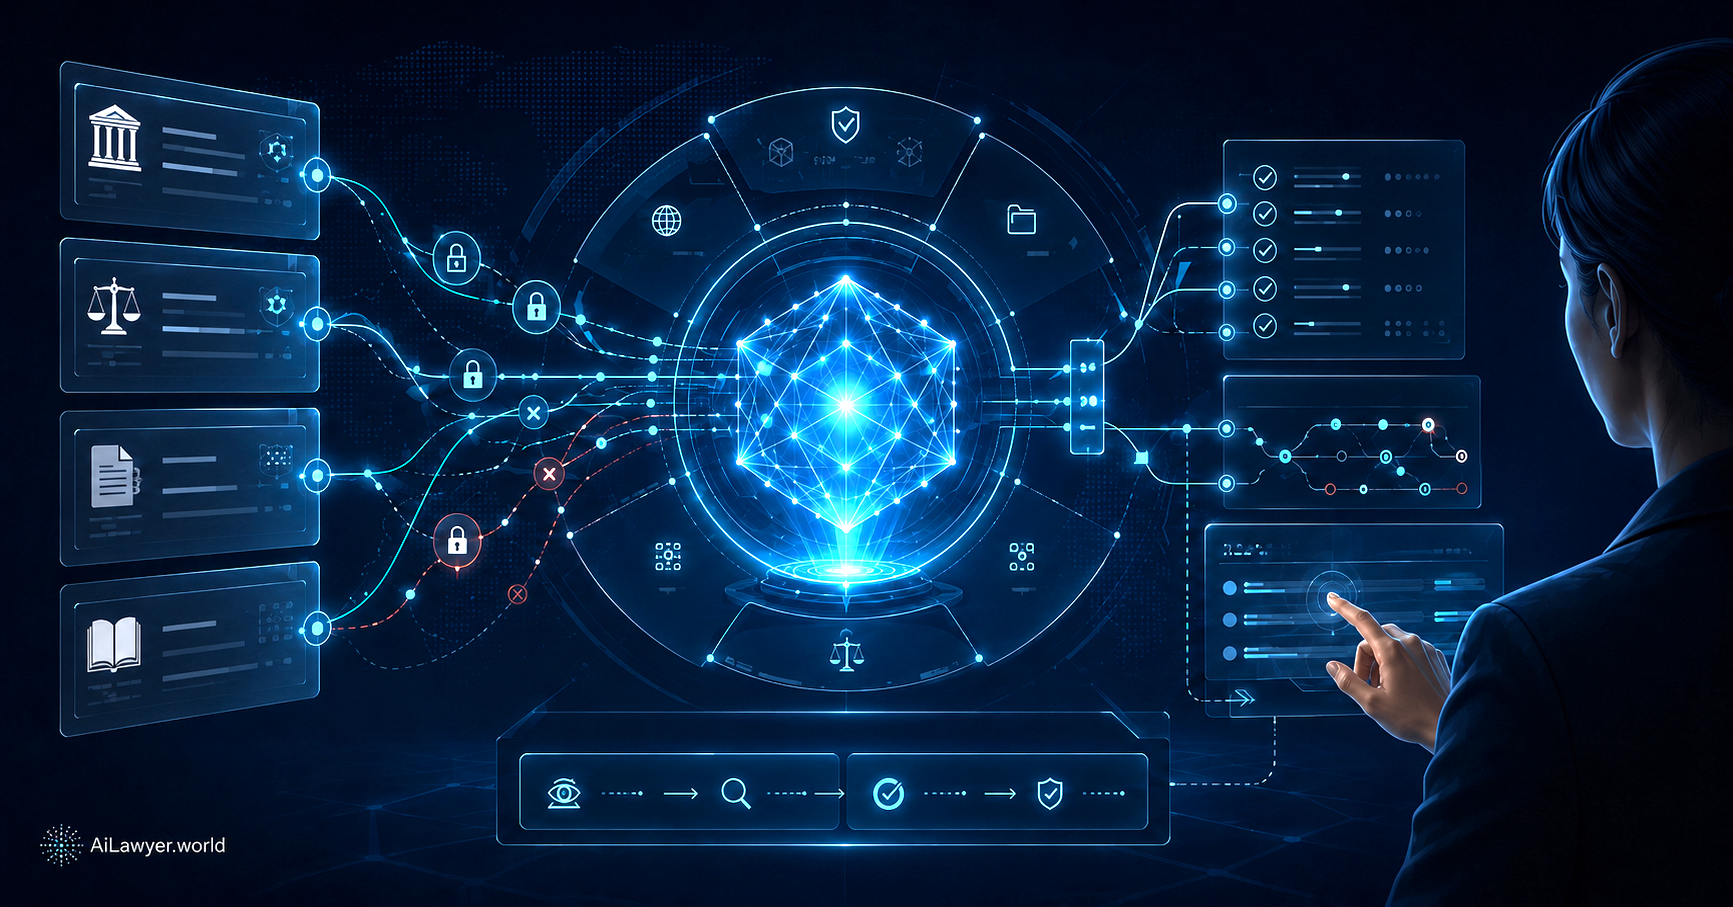
“Model + specialized knowledge + legal sources + workflows + access controls + verification.”
That difference matters.
A language model can generate an answer.
A legal system must also provide reasons to determine whether that answer can be trusted.
Legal AI is becoming infrastructure
A similar direction can be seen elsewhere.
On August 20, 2026, Thomson Reuters announced the next generation of CoCounsel Legal.
The system brings together legal research, analysis, drafting, legal intelligence and verification within an environment connected to professional resources such as Westlaw and Practical Law.
This represents a significant evolution from the idea of AI as an isolated chatbot.
Legal AI is increasingly becoming an infrastructure layer inside professional legal workflows.
The same trend is visible outside the United States.
In Russia, Yandex has been developing its specialized NeuroLawyer service together with access to materials from the GARANT legal information system. The service can work with legal questions and documents while providing references to professional legal materials.
Yandex has also integrated NeuroLawyer into Microsoft Word, moving AI assistance directly into the environment where legal documents are actually prepared.
Different companies are approaching the problem in different ways, but the direction is similar:
Legal AI is moving closer to verified knowledge systems and professional workflows.
More capable AI does not eliminate the verification problem
Greater capability does not automatically produce greater reliability.
On August 24, 2026, Reuters reported that the U.S. Court of Appeals for the Fifth Circuit was considering whether to reassign a case from U.S. District Judge Henry Wingate after an error-laden July 2025 order from his court had been partially drafted with AI assistance.
Wingate later said that a law clerk had used Perplexity and attributed the failure to a lapse in human oversight.
The central issue was not simply that AI had been used.
The deeper problem was that:
AI-generated material entered a legally significant document without adequate verification.
That distinction is critical.
An AI system may produce language that looks authoritative, coherent and legally sophisticated.
None of those qualities proves that the underlying information is correct.
Persuasive language is not the same as legal reliability
The DoNotPay case provides another useful example.
In February 2025, the US Federal Trade Commission finalized an order against DoNotPay, a service that had promoted itself using claims associated with an “AI lawyer” or “robot lawyer.”
The FTC prohibited the company from making claims that its service performed like a human lawyer without sufficient evidence to support those claims.
The order also required monetary relief of $193,000 and notification to certain former subscribers.
According to the FTC, DoNotPay had not performed the testing necessary to substantiate claims that its AI service could perform legal tasks at the level of a human lawyer.
The case illustrates a distinction that is especially important in law:
The ability to generate legal-sounding text is not evidence that the text is legally reliable.
For Legal AI, fluency cannot be the final standard.
The next stage is verification, not bigger promises
Law is a domain in which mistakes can have real consequences.
For that reason, a trustworthy Legal AI system should be able to answer more than:
“What is the rule?”
It should also support questions such as:
Where did this rule come from?
Which jurisdiction does it belong to?
When did it become effective?
Is it still in force?
Does it apply to this particular situation?
Are there exceptions?
Which part of the answer comes from a source, and which part is an inference by the model?
These questions move Legal AI beyond generation.
They move it toward governed legal knowledge.
A legal system should distinguish between a current rule and an outdated version. It should expose limitations and exceptions. It should preserve source provenance. And when the available evidence does not justify a confident answer, the system should be able to say so.
Sometimes the correct behavior of an intelligent system is not to produce more text.
Sometimes it is to identify a boundary.
The AiLawyer.world position
AiLawyer.world has gradually arrived at the same conclusion.
Earlier generations of legal AI development often concentrated on the visible capabilities of the model:
How well can it answer?
How quickly can it generate?
How many questions can it handle?
Those capabilities remain useful.
But the current direction of AiLawyer.world places greater emphasis on a different set of properties:
boundaries, verifiability, provenance, evidence, applicability and human oversight.
This does not mean reducing the role of artificial intelligence.
It means recognizing that the more capable AI becomes, the more important the architecture around it becomes.
The relevant question is no longer only:
What can the model generate?
It is also:
What does the system know, how does it know it, and where does the permissible inference end?
That distinction is central to our current research.
It is also the reason behind our broader principle that Legal AI should begin with boundaries rather than promises.
From retrieved information to governed legal knowledge
Retrieval is part of the solution, but retrieval alone does not solve the legal reliability problem.
A system may retrieve a document and still fail to understand whether that document belongs to the correct jurisdiction, whether it is still effective, whether an exception applies, or whether another legal authority supersedes it.
This is why the architecture around retrieved legal information matters.
At AiLawyer.world, one research direction is the concept of a structured legal knowledge unit in which a rule is connected to its source, jurisdiction, effective dates, applicability, exceptions, verification status and retrieval metadata.
A REG-container—short for Rule-Evidence-Grounded container—is a structured, versioned legal knowledge unit that stores a legal rule together with its official source, jurisdiction, effective dates, applicability, exceptions, verification status, and retrieval metadata.
RAG describes how a system retrieves information for generation; a REG-container defines the governed legal knowledge unit being retrieved.
The objective is not to claim that such architecture makes AI infallible.
It does not.
The objective is narrower and more defensible:
make the basis of a legal answer more inspectable and controllable.
That changes the role of AI.
Instead of presenting generated language as an endpoint, the system treats generation as one stage inside a larger evidence and verification process.
AI and human lawyers do not have to be competitors
There is another consequence of this approach.
Artificial intelligence and professional lawyers do not necessarily need to be treated as competitors.
A more sustainable model may be collaborative.
AI can help search, organize and analyze large amounts of information. It can compare documents, identify potentially relevant material and assist with drafting.
A human professional can step in when a situation requires judgment, responsibility, interpretation, strategic assessment or action beyond the boundaries of the system.
The broader AiLawyer project also maintains a separate human legal consultation channel on AiLawyer.ru. Our design direction preserves a path to human assistance rather than treating AI as a substitute for professional judgment.
AI can be the first level of interaction.
But it does not need to pretend to know everything.
In some cases, the correct output of an intelligent legal system should simply be:
Human review is required here.
That is not a failure of intelligence.
It is evidence that the system understands its limits.
From promises to an architecture of trust
Legal AI has already moved through an important first phase.
The early phase was largely about demonstrating capability:
Look — artificial intelligence can produce legal text.
The next phase presents a much harder challenge:
Can we explain why this particular result should be trusted?
That is where sources, provenance, jurisdiction, effective dates, applicability, version control, verification mechanisms and human responsibility become central.
This is also where the difference between a convincing demonstration and a dependable legal system begins to emerge.
The future of Legal AI will certainly depend on better models.
But better models alone will not be enough.
The systems around those models will matter just as much.
For legal artificial intelligence, we therefore believe the better starting point is not the promise that AI will replace lawyers.
It is a more difficult question:
What boundaries must a Legal AI system respect before its output can be meaningfully verified?
Our principle can be stated simply:
Boundaries and evidence first. Capabilities second.
Russian version on AiLawyer.ru
Sources and further reading
- Google Cloud — “Introducing Gemini Enterprise for Legal,” August 25, 2026. Google Cloud — Gemini Enterprise for Legal
- Thomson Reuters — Next Generation of CoCounsel Legal, August 20, 2026. Thomson Reuters — CoCounsel Legal
- Yandex — NeuroLawyer and GARANT. Yandex — NeuroLawyer and GARANT
- Yandex — NeuroLawyer for Microsoft Word. Yandex — NeuroLawyer for Microsoft Word
- Reuters — judicial AI use case, August 24, 2026. Reuters — judicial AI use case
- Federal Trade Commission — Final DoNotPay order, February 2025. FTC — DoNotPay AI Lawyer order
- AiLawyer.world. AiLawyer.world — international research and evidence layer.
- AiLawyer.world. Why Legal AI Should Start With Boundaries, Not Promises — boundaries and evidence-first research.
- AiLawyer.world. Evidence — project evidence and chronology.
- AiLawyer.world. Legal Lab — laboratory materials.